THE INFERENCE RIG
Local GPUs and one router, so I own the token supply
The Problem
Running a fleet of autonomous agents means running a lot of inference. The frontier model handles the complex reasoning, but much of the volume is cheaper, repetitive work: alert vetting, draft scoring, embedding queries, routing decisions. At cloud API rates that volume adds up fast. More importantly, it adds up unpredictably.
Cost wasn't the only problem. An agent that sends every observation to a cloud endpoint has no privacy boundary. Security telemetry is sensitive, and the knowledge graph stores personal context. Those workloads needed inference that never left the building, and I treated that as a design requirement, not a preference.
I already had the GPUs. The question was whether open-weights models at the right size could carry frontier-adjacent quality for the workloads that actually needed it.
The Solution
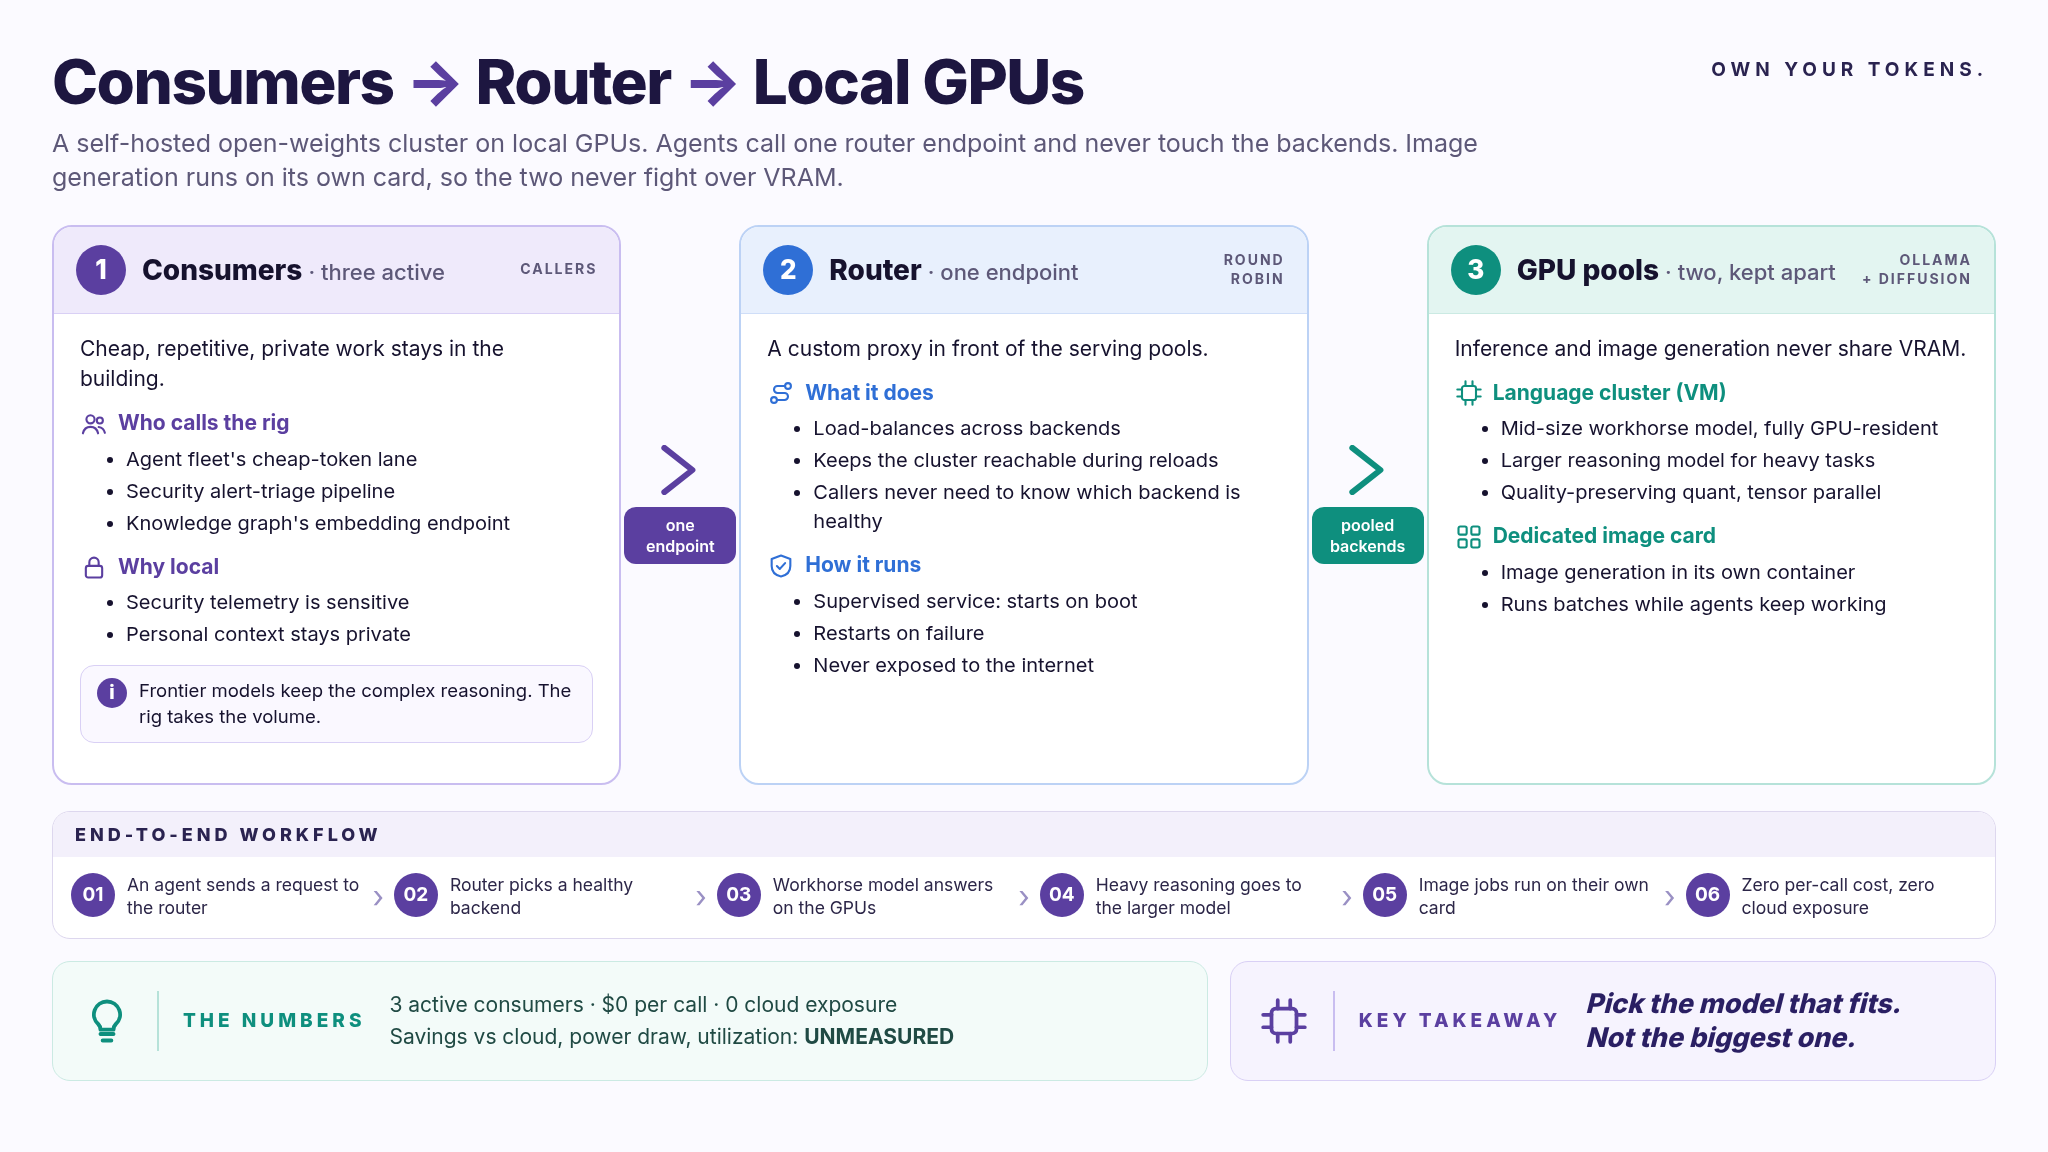
The cluster runs as a virtual machine on a dedicated AI host. Its GPUs are pooled and load-balanced, and a custom round-robin router sits in front of the pools as a supervised service. Consumers call the router endpoint and never touch the backends directly.
Two model lanes run on it today. The workhorse is a mid-size open-weights model. It stays fully GPU-resident, it's fast enough for interactive agent calls, and it handles classification, vetting and draft generation. A larger reasoning model takes the heavier reasoning tasks.
Own your tokens: no per-call cost, no privacy boundary crossed, and no vendor outage spilling into agent downtime.
Image generation runs on a separate GPU in its own container, so inference and diffusion never compete for the same VRAM. I split them on purpose. The language cluster serves inference, the dedicated card serves image generation, and each can saturate its own hardware.
Craft Details
The quantization tradeoff. Not all quants are equal. During setup, an aggressive quantization on a single GPU ran faster than a quality-preserving one split across GPUs, but its output was unusable for the downstream agents that depended on it. How aggressive a quant is interacts with model architecture in ways raw throughput benchmarks don't capture. The best setup turned out to be a quality-preserving quant with tensor parallelism across cards. Quality and throughput aren't always at odds. With the right pairing you get both.
The context-window lesson. The serving layer shipped with a small default context window. Several downstream agents started failing silently. Their prompts were longer than the default, so they got truncated, malformed outputs with no error signal. Once I found the cause, the fix was simple: size the context limit to the real workloads. The bigger lesson came from the audit that found it. Agents need explicit context-window contracts, and "it runs" isn't the same as "it runs on the inputs it will actually receive."
vLLM and the pragmatism decision. I evaluated vLLM as an alternative serving layer for its better batching and higher theoretical throughput. At the time it was blocked on architecture support for the model families I was using. Ollama shipped, vLLM didn't. The rule I took from it: pick the tool that runs today over the one that's theoretically better but isn't ready. Infrastructure that works beats infrastructure that's optimal.
The router. With one round-robin proxy in front of the serving pools, consumers don't need to know how many backends exist or which one is healthy. When a backend needs a model reload or a restart, the router keeps the cluster reachable. It runs as a supervised service that starts on boot and restarts on failure, and the cluster is never exposed to the internet.
Stack
Result
The rig serves three active consumers today: the agent fleet's cheap-token lane (classification, routing, draft scoring), the security alert-triage pipeline, which triages alerts locally before they reach the operator, and the knowledge graph's embedding endpoint. All three run at zero per-call cost and zero cloud exposure.
The per-token savings versus a cloud API are real but UNMEASURED. I didn't baseline cloud spend before switching, so there's no clean comparison. What I can measure: the alert-triage pipeline runs with no cloud dependency and no per-call cost, verified end to end by synthetic event injection. Power draw and utilization percentage are also UNMEASURED.
Keeping diffusion and inference apart paid off right away. An image-generation batch on the dedicated card runs while the language cluster handles agent traffic, with no VRAM contention and no queue stalls. Each of the two GPU pools runs at its own ceiling.
Pick the model that fits your VRAM, your hardware and the context window your agents actually need, even when it isn't the biggest one.